Researchers · Interviewed at COLM 2026
Clara Meister
EPFL
COLM 2026 · October 11, 2026 · 9 min
COLM 2026 in SF | The Tokenizer Before the Tokenizer: How One Regex Line Can Make or Break Models
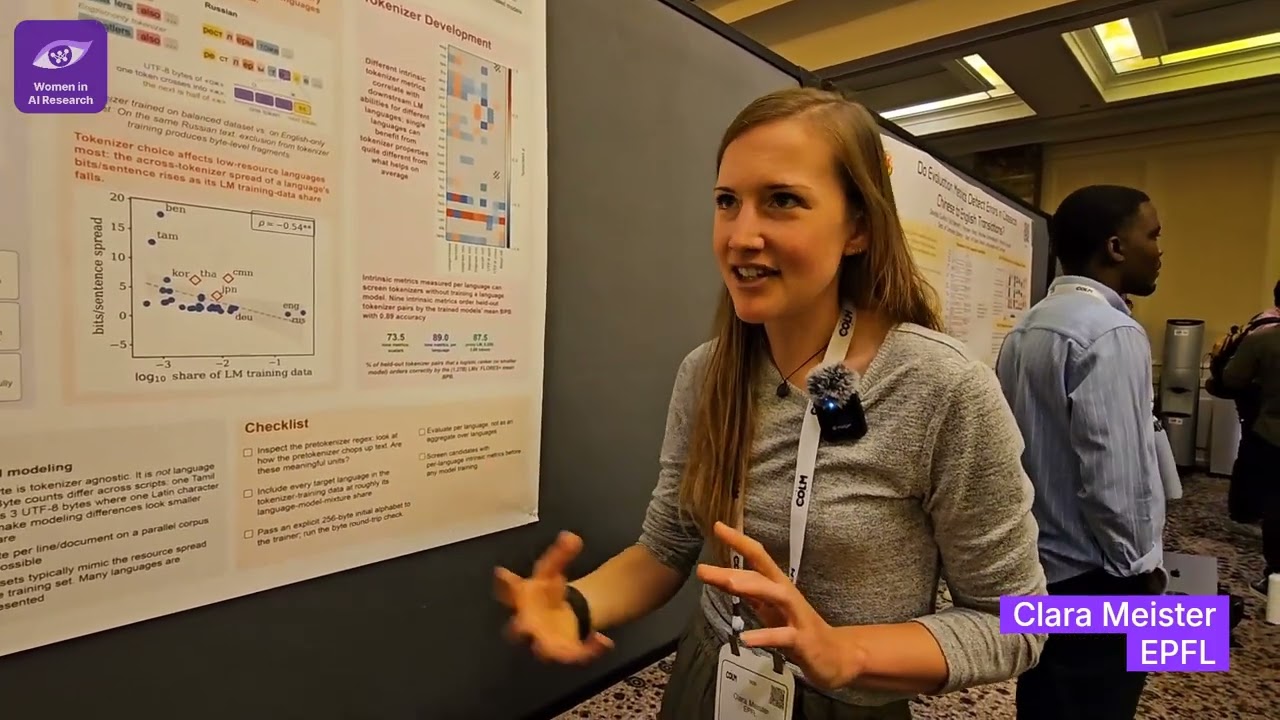
Recorded live at COLM 2026, the Conference on Language Modeling. Clara Meister (Postdoc, EPFL) joins Jekaterina Novikova to talk about TokEval, her new library for measuring tokenizers directly on text - and what controlled pretraining experiments reveal about when tokenization actually matters.
Two findings stand out. For code, the decisive choice is not the tokenizer algorithm but the pre-tokenizer - the "tokenizer before the tokenizer", a long regex that decides where tokens are never allowed to cross. Changing a single whitespace clause produced a large jump in Python pass@1 across seeds. For multilingual models, swapping the tokenizer barely moves English, but causes a wide spread in performance for languages with less training data. The practical upshot: you can tailor your tokenizer for low-resource languages without really hurting English.
More from COLM 2026
All event interviews →- Emmy LiuCarnegie Mellon University
- Jocelyn ShenGoogle DeepMind
- Christina BaekCarnegie Mellon University / DatologyAI
- Nan HuangUC San Diego
- Chantal ShaibMIT
- Diana AbagyanCohere Labs
- Aruna SankaranarayananMIT
- Muxin LiuUniversity of Pennsylvania
- Akhila YerukolaCarnegie Mellon University
- Chandreyi (Zini) ChakrabortyGeorgia Tech
- Myra ChengStanford University
- Kimia HamidiehMIT