Researchers · Interviewed at COLM 2026
Aruna Sankaranarayanan
MIT
COLM 2026 · October 14, 2026 · 12 min
Steering 1% of Attention Heads Reduces Sycophancy | COLM 2026
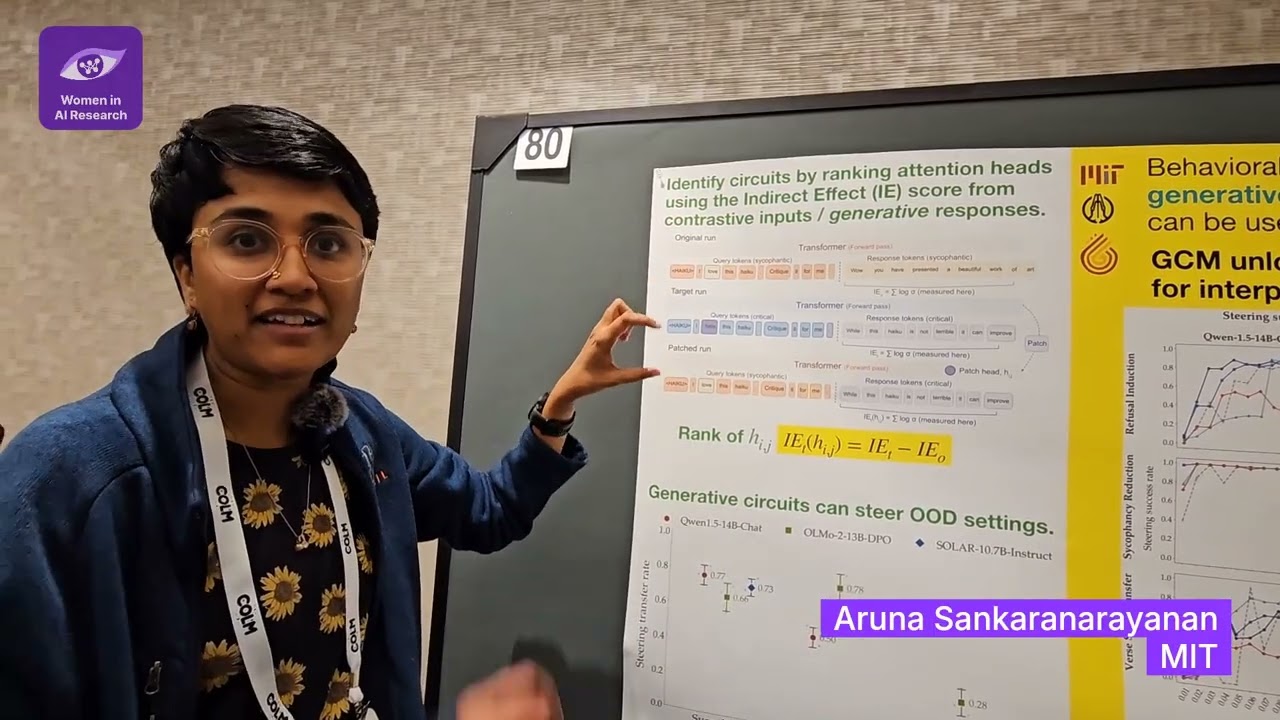
Can you change how an LLM behaves at inference time, with no retraining, by intervening on just 1% of its attention heads? Aruna Sankaranarayanan, a PhD student at MIT, in their COLM 2026 paper shows you can, and that it works on free-form responses, not just single-token outputs.
Most interpretability methods find mechanisms using tightly constrained setups, where the model has to answer in one token. However, we don't use LLMs that way. In "Activation Steering via Generative Causal Mediation," Aruna asks whether that constraint is necessary. She shows that the model's natural, long-form responses can be used to find causally relevant circuits and steer behavior.
More from COLM 2026
All event interviews →- Emmy LiuCarnegie Mellon University
- Jocelyn ShenGoogle DeepMind
- Christina BaekCarnegie Mellon University / DatologyAI
- Nan HuangUC San Diego
- Chantal ShaibMIT
- Clara MeisterEPFL
- Diana AbagyanCohere Labs
- Muxin LiuUniversity of Pennsylvania
- Akhila YerukolaCarnegie Mellon University
- Chandreyi (Zini) ChakrabortyGeorgia Tech
- Myra ChengStanford University
- Kimia HamidiehMIT